PairHint today
Several AI models work together to listen, see the screen, remember context and answer in real time. Coordinating them adds integration work, processing overhead and delays.
PairHint is an on-device, real-time AI copilot for high-stakes conversations. It listens, sees your screen and remembers your documents, with no cloud round trip and nothing leaving the machine. Live today on macOS, Apple Silicon and Intel.
Seed round
to go-to-market once funded
paying users by end of year 1
paying users 6-year projection
Why PairHint is different: Capturing audio and screen and answering in real time is far harder than it looks. That difficulty is the moat.
Zero cloud hosting costs, zero data tracking. Runs local GGUF models directly on user GPUs/CPUs via optimized C++ bindings.
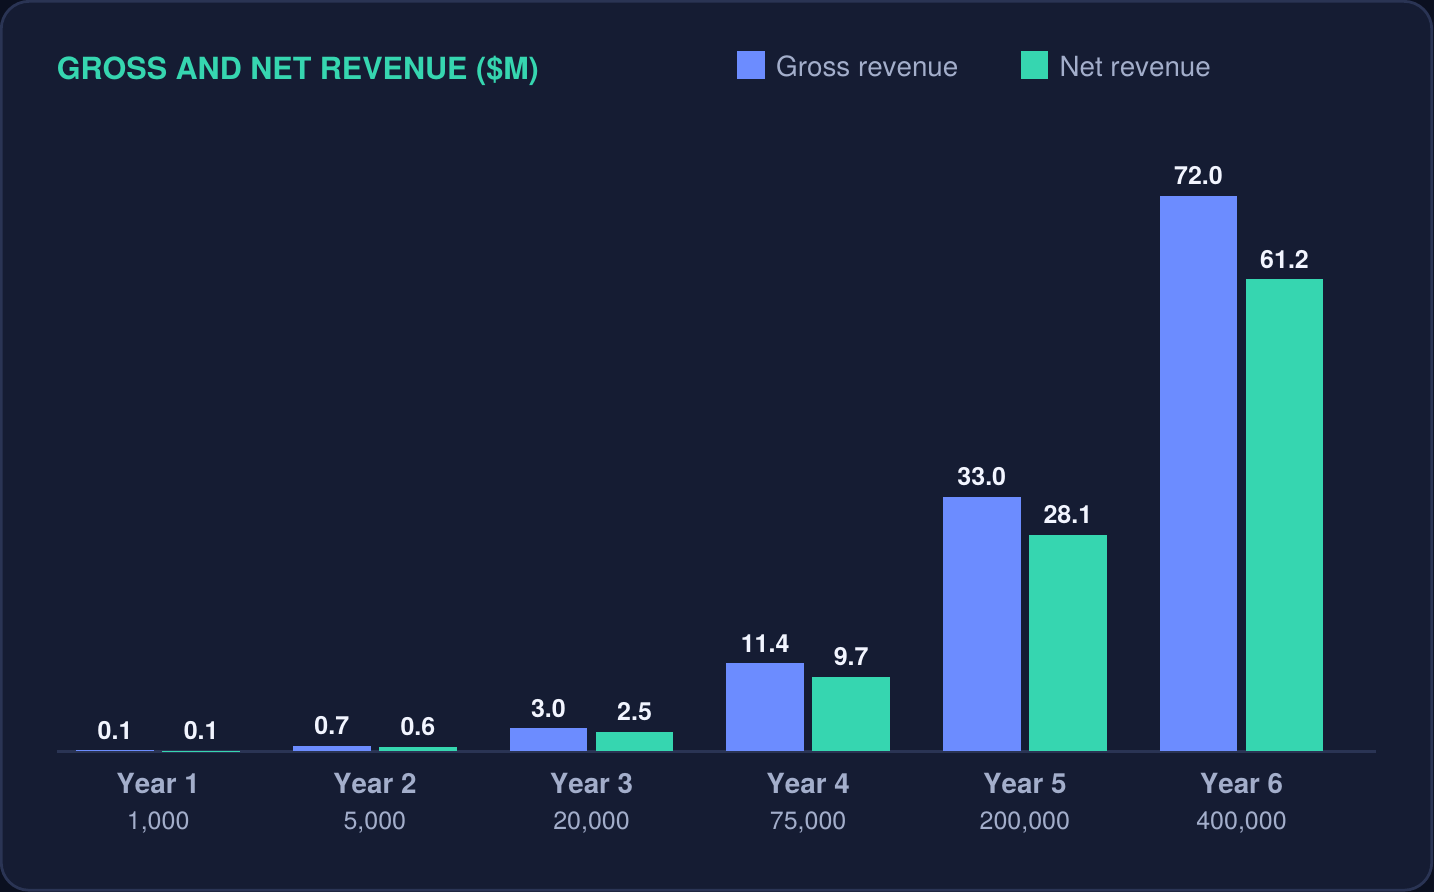
Subscription plus session-hour top-ups, with local inference so each new user adds little marginal cost. Planning assumption: 85% of gross revenue kept after fees, refunds, hosting and support.
Expanding beyond meetings into Medical clinical notes, Legal depositions, Enterprise Sales, and Field Engineering.
Planning case at a $20/month blended price: 20K paying users and $3.0M gross revenue in year 3, 200K users and $33.0M in year 5. Teams, enterprise and platform revenue are not included.
Choose between speech engines (AUTO multi-STT) and AI engines (LLM1 Best, LLM2 Good) to balance accuracy and speed for each question, and freeze an answer on screen when needed.
No server GPU fleet to fund. The seed goes to product and AI (40%), go-to-market (35%) and trust and scale (25%).
The reusable asset is the pipeline itself: capture, context, inference and presentation, all tuned for latency.
Microphone and meeting audio on two channels, with noise filtering and live question detection.
Reads problem statements, diagrams and documents straight from the shared screen.
Uploaded documents, role and presentation context, and the conversation so far.
A one-line answer first, then key points, code, complexity and follow-ups, streamed while the conversation continues.
Designed for live conversations across professional roles in sales, consulting, law, healthcare, technical support, and engineering.
52M jobs in six live-conversation roles across 4 global regions.
~25M jobs in sales, consulting, law, and technical support.
Year-6 revenue target (400K paying users): 1.2% of SAM, 0.6% of TAM.
Capturing audio and screen and answering in real time is far harder than it looks. That difficulty is the moat.
| Chat AI | Meeting assistants | PairHint | |
|---|---|---|---|
| Live audio awareness | User-provided | Meeting-focused | Dual-channel capture |
| Screen context | Manual upload | Varies | Screen analysis + OCR |
| Personal documents | Files / prompts | Limited | Persistent session context |
| Technical output | General | General | Code + explanations |
| Privacy model | Cloud | Cloud | On-device |
| Interface | Separate window | Meeting UI | Floating overlay |
Planning case: 400,000 paying users and $72M gross revenue by year 6, about 1.1% of professional developers.
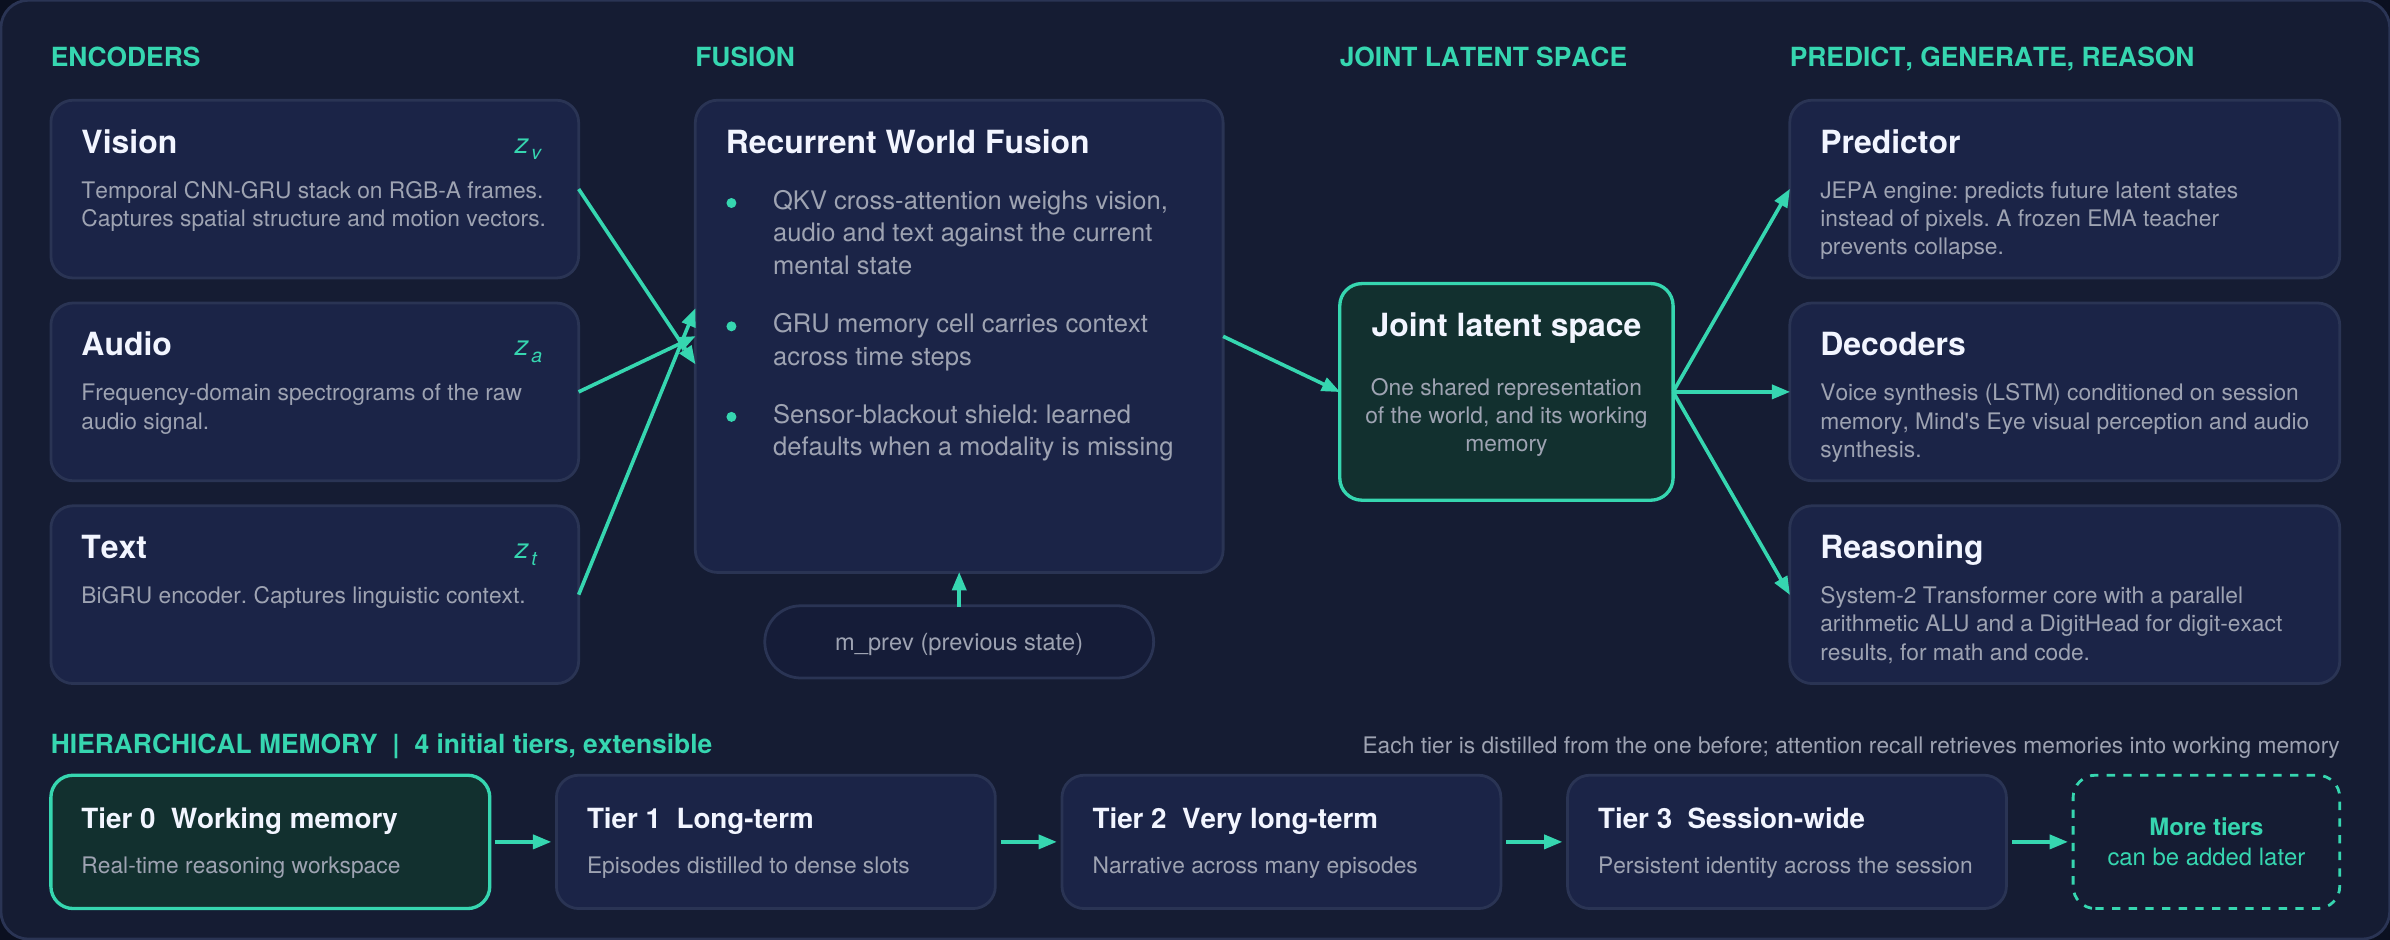
GENTA is our research project for a compact, general-purpose AI model. It brings together images, speech and text, multiple levels of memory, reasoning and content generation in one architecture. PairHint provides a concrete first application; GENTA’s potential goes much further.
Several AI models work together to listen, see the screen, remember context and answer in real time. Coordinating them adds integration work, processing overhead and delays.
Bring perception, memory, reasoning and response generation together in one compact model. The aim is faster responses, lower running costs and easier deployment on local devices.
Combines images, speech and text so the model can use information from them together.
JEPA, a predictive learning approach, trains the model to anticipate what comes next from the information it observes.
Working and short-term context, plus long-term and very long-term memory, help the model use earlier information.
Symbolic reasoning uses explicit mathematical operations to improve reliability. Generation capabilities span text, speech, images, 3D objects and video.
An initial 65 training tasks develop different skills within one model, providing a foundation for broader applications.
Multiple synchronized instances train together and share learning updates, designed to accelerate learning across multiple processors.
The same architecture could support education, professional assistants and creative tools. Improvements to the shared model could benefit multiple products, opening opportunities beyond a single application.
PairHint is the near-term business. GENTA is the longer-term research opportunity; efficiency and full product integration remain development goals.
Are you an Angel Investor, VC Partner, or Strategic Fund? Connect directly with the founder.